<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><link href="https://0x1.pt/feed.xml" rel="self" type="application/atom+xml" /><link href="https://0x1.pt/" rel="alternate" type="text/html" /><updated>2026-09-06T00:00:00+00:00</updated><id>https://0x1.pt/feed.xml</id><title type="html">0x1</title><subtitle>Software engineer. Built healthcare and recruitment software. Interested in finance, economics and policy.</subtitle><author><name>Vitor Sousa Pereira</name></author><entry><title type="html">From Jekyll to a POSIXish Static Site Generator</title><link href="https://0x1.pt/2026/09/06/from-jekyll-to-posix/" rel="alternate" type="text/html" title="From Jekyll to a POSIXish Static Site Generator" /><published>2026-09-06T00:00:00+00:00</published><updated>2026-09-06T00:00:00+00:00</updated><id>https://0x1.pt/2026/09/06/from-jekyll-to-posix</id><content type="html" xml:base="https://0x1.pt/2026/09/06/from-jekyll-to-posix/"><![CDATA[<p>I started this blog back in 2021 and it has been generated by <a href="https://jekyllrb.com/">Jekyll</a> since then. As far as personal tech blogs go, that’s probably a record.</p>

<p>These days I don’t use Ruby to write code I own so having to keep it around and up-to-date just for this was more trouble than I was willing to go through.</p>

<p>I considered replacing it with <a href="https://github.com/osteele/gojekyll/">gojekyll</a>. It implements just enough of Jekyll for things to work and, like the name implies, it’s written in Go. That means it’s faster and you can just download a binary and drop it into your <code>bin/</code> directory to have it working.</p>

<p>That seemed like the best route but then I remembered a limitation of Jekyll that I didn’t like: the fact you can only have a single collection of posts. So, I can’t have two “blogs” on the same instance. Also, I wanted a more interesting solution.</p>

<p>So, instead, I decided to whip up a couple of LLMs to build myself something nice. Based on my experience, the better use of coding LLMs comes from having a top-of-the-shelf model generate a plan for a lesser model to implement. I passed this prompt to Fable 5.1 (high):</p>

<blockquote>
  <p>This is my personal website and blog which uses the Jekyll static site
generator. I want to switch from Jekyll to a custom system that uses only tools
that can be found on a POSIX-compliant system like sh, awk, sed, …</p>

  <p>Ideally, the system must be fully self-contained in this repo. This mean we’ll
need to implement, at least, a markdown to html renderer and an http server for
development (<code>jekyll serve</code>). Only if this is nigh-impossible should we use a
third-party library.</p>

  <p>Existing URLs MUST be kept stable. E.g.
  <code>/_posts/2025-04-06-the-insanity-of-being-a-software-engineer.md</code> is accessible at
  <code>/2025/04/06/the-insanity-of-being-a-software-engineer/</code> and must be kept like
that. Same for the other files.</p>

  <p>We don’t need SCSS. Just convert our style files to plain CSS.</p>

  <p>We don’t need to support Jekyll plugins but we need to keep the functionality we
already have. Namely:</p>

  <ol>
    <li>CSS inlining</li>
    <li>RSS feed</li>
    <li>SEO fields</li>
    <li>Generated <code>sitemap.xml</code></li>
  </ol>

  <p>Jekyll supports a single posts dir at <code>/_posts/</code>. It would be great if could have
any number of these. E.g. I may want to add another “blog” separate from my
existing one for TILs.</p>

  <p>Liquid is used for templating. We do need a templating system but it doesn’t
need to be as powerful as Liquid. It just needs to implement what we use. If
needed, we can opt for a different syntax (e.g. for frontmatter).</p>

  <p>You might want to add tests. Use the self-contained version of
  <a href="https://codeberg.org/sstephenson/brat#embedding-brat-in-your-project">https://codeberg.org/sstephenson/brat#embedding-brat-in-your-project</a></p>

  <p>Write the plan to <code>PLAN.md</code>. Use 2 space indents. Max line-length of 80-chars.</p>
</blockquote>

<p>And then I had Opus 5 (medium) implement the plan.</p>

<p>The result was pretty cool. It implemented a bunch of things in AWK:</p>

<ul>
  <li>A Markdown to HTML renderer that supports all of the syntax I’m using – which is most of it. It includes a lexer for syntax highlighting code blocks.</li>
  <li>A small template engine that parses the subset of Liquid syntax I’m using.</li>
  <li>Site and dir settings in <code>.conf</code> files instead of YAML. These can just be sourced into shell scripts.</li>
  <li>Automatic RSS feed and Sitemap generation.</li>
  <li>An HTML and CSS minifier. I didn’t ask for it but I was using <a href="https://jch.penibelst.de/">Compress HTML in Jekyll</a>. Fable decided to include it in the plan.</li>
</ul>

<p>AWK was built to transform text. It takes input text, manipulates it and turns it into (different) output text. So, it makes sense it was used.</p>

<p>To orchestrate all the AWK scripts, it wrote a bunch of POSIX shell scripts.</p>

<p>It solved the multiple collections issue. Now, if I drop a <code>collection.conf</code> into a dir with a couple of fields, that whole directory becomes a collection.</p>

<p>The only hiccup came in <code>bin/serve</code>. Fable’s plan was to use good old netcat to open multiple sockets to be served by a shell script that returned the requested file with the appropriate headers like <code>Content-Type</code>, <code>Content-Length</code> and so on. Unfortunately, this didn’t work.</p>

<p>Chrome opens several parallel connections to your server so it can request many assets in parallel – at least in HTTP 1.1, maybe it’s different for later versions. This is fine. But it turns out it does more than that. It may also speculatively open additional connections and just hang on to them. They may or may not eventually be used. This is great for users because if the connection’s needed it can immediately be used, no need to wait for TCP and SSL handshakes. But it cause the netcat process to block.</p>

<p>I had to compromise and settled on a forking web server written in Perl. Interestingly, while this did make our new system less POSIXy it didn’t make it that much less portable. It turns out that Perl is available by default on a bunch of platforms. macOS has it by default. Ubuntu as well. Even Arch includes it in <code>base</code>. And the web server won’t execute when deploying the website on Netlify so that part’s still all very POSIX.</p>

<p>Speaking of Netlify, this change came with an unexpected bonus. The build time decreased from 3m20s to just 12s. That’s almost <strong>17x</strong> faster. I think that’s mostly due to the fact that Ruby does not need to be installed as part of the deployment.</p>

<p>To ensure correctness, the output of <code>jekyll build</code> was used as a reference and several tests were written against it. A total of 90 tests were added to cover most functionality. <a href="https://codeberg.org/sstephenson/brat">Brat</a>, authored by Sam Stephenson of Rails fame, is used as a test runner. It’s totally self-contained in a single script.</p>

<p>Overall, I’m very happy with the result. Instead of feeling like a blog, now this static site feels like living software. I chose not to make everything open-source just because I’d prefer not to make my drafts public. You can probably issue the prompt above on your own Jekyll repo and get a similar result.</p>]]></content><author><name>Vitor Sousa Pereira</name></author><summary type="html"><![CDATA[Asking AI to build me custom static site generator using only tools available in most POSIX systems.]]></summary></entry><entry><title type="html">The Insanity of Being a Software Engineer</title><link href="https://0x1.pt/2025/04/06/the-insanity-of-being-a-software-engineer/" rel="alternate" type="text/html" title="The Insanity of Being a Software Engineer" /><published>2025-04-06T00:00:00+00:00</published><updated>2025-04-06T00:00:00+00:00</updated><id>https://0x1.pt/2025/04/06/the-insanity-of-being-a-software-engineer</id><content type="html" xml:base="https://0x1.pt/2025/04/06/the-insanity-of-being-a-software-engineer/"><![CDATA[<p>Is something I think about often because I can’t help but wonder if most other jobs are like this.</p>

<p>Being a software engineer is tough. You need to know a couple of programming languages and tools right from the get-go. But that won’t cut it. Companies expect you to know whatever particular framework they use. That might be Rails or Django or Laravel or something else. You’ll also need CSS. It’ll take you a lifetime to learn — and you still won’t know why the layout’s breaking — but knowing just enough to get by is feasible.</p>

<p>It’s unlikely that you won’t have to deal with JavaScript. Maybe you’re lucky and you just need to sprinkle in the occasional jQuery in the legacy app you’re maintaining. But things change.</p>

<p>At some point, the people at Facebook built React. Turns out that company with tens of thousands of engineers had two specialties all along: front-end and back-end. The programming hive-mind collectively decides that React is now the right way to build software but, at the same time, companies decide they can’t afford more engineers. Lo and behold the full-stack engineer is born and you’re it. Get to learning React and building REST APIs on top of the back-end tech you already know.</p>

<p>It won’t stop there. You know you need types, right? Add TypeScript. Are you really going to be managing state in React like a pleb? Add Redux. Feeling smart because you dodged both of those? Have fun figuring out to how to configure webpack/esbuild/rollup, plus Prettier, plus ESLint.</p>

<p>“Ok”, you say. “But I can keep doing things the way that I’ve been doing them. It worked fine. I don’t need React”. Of course you can. You can absolutely deviate from the way things are done everywhere in your fast-moving, money-burning startup. Just tell your boss that you’re available to teach the new hires — who’ve only ever heard of React — about the joys of server-side rendering.</p>

<p>Oh and, turns out we were just getting started.</p>

<p>Back when dinosaurs roamed the earth there was a type of professional called a System Administrator. Their whole job was to make sure that your backend was working nicely. They handled infrastructure changes, upgrading the database, system upgrades, keeping the daemon running, restarts, everything. Then came DevOps. Some cash-strapped company somewhere decided that now all of this would be handled by the engineers and everyone agreed. Now you need to learn Docker. Oh, your whole app is just a single statically linked binary and you don’t need Docker? Learn Ansible and I hope you have fun figuring out the options you need to pass to SystemD.</p>

<p>And you’re not even halfway there. Now you gotta learn AWS. You won’t be using the GUI to configure your infrastructure like a peasant so you better learn Terraform or Pulumi or whatever.</p>

<p>You do a good job. You’re promoted to manager. You need to learn a whole other job. But that’s ok because it’s the end-game. Bliss. Here’s some of the stuff you’ll need to do:</p>

<ol>
  <li>Guesstimate deadlines</li>
  <li>Assign tasks to teammates</li>
  <li>Spec tasks</li>
  <li>Participate in annual reviews</li>
  <li>Provide valuable feedback during product meetings</li>
</ol>

<p>You better hope your company has quadrupled in number of employees by this point or you’ll be doing management plus all of the above.</p>

<p>And it can always get worse. A recruiter reached out to me a couple of days ago about an engineering position for a secret company. They decided that they required senior level skills in Rails, Hotwire and, incredibly, native mobile development. Why not add kernel and compiler development in there as well for good measure?</p>

<p>Software gets more complicated. All of this complexity is there for a reason. But what happened to specializing? When a house is being built, tons of people are involved: architects, civil engineers, plumbers, electricians, bricklayers, interior designers, roofers, surveyors, pavers, you name it. You don’t expect a single person, or even a whole single company, to be able to do all of those.</p>

<p>Maybe a future where we can build a whole app with a couple of prompts isn’t so bad.</p>]]></content><author><name>Vitor Sousa Pereira</name></author><summary type="html"><![CDATA[Is something I think about often because I can’t help but wonder if most other jobs are like this.]]></summary></entry><entry xml:lang="pt-PT"><title type="html">Leituras Recentes — Janeiro 2025</title><link href="https://0x1.pt/2025/01/04/leituras-recentes-janeiro-2025/" rel="alternate" type="text/html" title="Leituras Recentes — Janeiro 2025" /><published>2025-01-04T00:00:00+00:00</published><updated>2025-01-04T00:00:00+00:00</updated><id>https://0x1.pt/2025/01/04/leituras-recentes-janeiro-2025</id><content type="html" xml:base="https://0x1.pt/2025/01/04/leituras-recentes-janeiro-2025/"><![CDATA[<p><strong>A Intendência-Geral do Orçamento</strong> de Nuno Ivo Gonçalves – Relata a história da Intendência-Geral do Orçamento, uma instituição criada para avaliar a correcção económica das propostas de lei. A instituição foi concebida em 1929 mas nunca deixou o papel. Até hoje, as suas competências não estão atribuídas a qualquer outra instituição, para grande prejuízo da nossa economia. O livro é extraordinariamente académico e tem imensas transcrições de leis, correspondência e afins.</p>

<p><strong>Alfredo da Silva: Biografia</strong> de Miguel Figueira de Faria – Biografia do mais conhecido industrialista Português, o homem que fundou a Companhia União Fabril (CUF), a Tabaqueira, entre outras. A CUF ainda existe hoje, se bem que muito diferente. O que achei mais impressionante foi que Alfredo da Silva fundou e geriu muitas das suas empresas em tempos de grande agitação civil e política. Também as geriu à distância durante algum tempo em que esteve exilado. A leitura não é muito interessante mas gostei do livro.</p>

<p><strong>Anatomia de Uma Revolução</strong> de António Barreto – O melhor e mais interessante livro sobre o 25 de Abril que já li. Escrito por António Barreto, Ministro da Agricultura no I Governo Constitucional. O livro é escrito sempre com o foco na Reforma Agrária e dos efeitos que esta teve. Altamente recomendado.</p>

<p><strong>Autobiografia Política: Parte 1</strong> de Aníbal Cavaco Silva – Escrito pelo Prof. Cavaco Silva não muitos anos depois de ter terminado o seu Governo. Narra a sua experiência como Ministro das Finanças e do Plano no Governo de Sá Carneiro, chegada à liderança do PSD e o primeiro Governo, minoritário, que formou. Num dos capítulos, descreve a forma de funcionar do Governo e, especialmente, do Conselho de Ministros. Só por este capítulo, já merece ser lido. Os Governos do Prof. Cavaco Silva foram os mais eficientes de todos, na minha opinião. A Parte 2 está na calha de leitura.</p>

<p><strong>O Primeiro-Ministro e a Arte de Governar</strong> e <strong>Uma Experiência de Social-Democracia Moderna</strong> de Aníbal Cavaco Silva – Ambos os livros acabam por ser condensações da experiência do Prof. Cavaco Silva como Primeiro-Ministro (e talvez como Presidente da República). O primeiro livro tem uma das frases que me fez aderir ao PSD: “A crise de identidade que afeta tantos partidos, não se coloca no PSD, que não precisa de ser de direita, nem de esquerda.”</p>

<p><strong>Direito para (Quase) Todos</strong> de João Caupers - Escrito pelo antigo Presidente do Tribunal Constitucional. É uma introdução aos principais aspectos da lei portuguesa para leigos. Escrito de uma forma muito simples e acessível mas pouco interessante.</p>

<p><strong>Francisco Sá Carneiro: Solidão e Poder</strong> de Maria João Avillez – Biografia do fundador do PSD, escrita por Maria João Avillez, um monumento do jornalismo português. Descreve a vida de Francisco Sá Carneiro e de todos os seus contributos para o país, sobretudo através da fundação do PSD.</p>

<p><strong>O Equívoco do 25 de Abril</strong> de Sanchez Osório – Neste livro, publicado ainda antes do 25 de Novembro, Sanchez Osório, militar envolvido no 25 de Abril, descreve, na sua perspectiva de cristão liberal, o regime soviético que se estava a instalar. Historicamente relevante mas não expõe muitos factos relevantes que um conhecedor da história do 25 de Abril já não saiba.</p>

<p><strong>Presos Por Um Fio: Portugal e as FP-25 de Abril</strong> de Nuno Gonçalo Poças – Nuno Gonçalo Poças conta a história das Forças Populares 25 de Abril, um grupo terrorista de extrema-esquerda liderado por Otelo de Saraiva Carvalho, um dos homens do 25 de Abril. Talvez (felizmente) o único exemplo de terrorismo real, organizado na história do país. Numa tentativa de sarar as feridas do 25 de Abril e esquecer o fervor revolucionário, todos os terroristas saíram impunes e o assunto foi varrido para baixo do tapete.</p>

<p><strong>Um Caminho para Portugal</strong> de Carlos Tavares and Sara Monteiro – Escrito por Carlos Tavares, Ministro da Economia no Governo de Durão Barroso, e Sara Monteiro, economista. O livro divide-se em duas partes. Na primeira, descreve momentos que constituíram reformas reais ou oportunidades de reforma económicas. Na segunda, os autores enumeram reformas necessárias para o país retomar a convergência económica com a União Europeia. O livro é prefixado por um prefácio do ex-Ministro Miguel Cadilhe que vale a pena ler. Altamente recomendado.</p>

<!-- Local Variables: -->
<!-- jinx-languages: "pt_PT-preao" -->
<!-- End: -->]]></content><author><name>Vitor Sousa Pereira</name></author><summary type="html"><![CDATA[A Intendência-Geral do Orçamento de Nuno Ivo Gonçalves – Relata a história da Intendência-Geral do Orçamento, uma instituição criada para avaliar a correcção económica das propostas de lei. A instituição foi concebida em 1929 mas nunca deixou o papel. Até hoje, as suas competências não estão atribuídas a qualquer outra instituição, para grande prejuízo da nossa economia. O livro é extraordinariamente académico e tem imensas transcrições de leis, correspondência e afins.]]></summary></entry><entry xml:lang="pt-PT"><title type="html">Review: 25 de Novembro sem Máscara</title><link href="https://0x1.pt/2024/12/15/review-25-de-novembro-sem-mascara/" rel="alternate" type="text/html" title="Review: 25 de Novembro sem Máscara" /><published>2024-12-15T00:00:00+00:00</published><updated>2024-12-15T00:00:00+00:00</updated><id>https://0x1.pt/2024/12/15/review-25-de-novembro-sem-mascara</id><content type="html" xml:base="https://0x1.pt/2024/12/15/review-25-de-novembro-sem-mascara/"><![CDATA[<p><img src="/assets/review-25-de-novembro-sem-mascara/foto.jpg" alt="25 de Novembro sem Máscara - Capa" class="mx-auto" width="400" height="425" /></p>

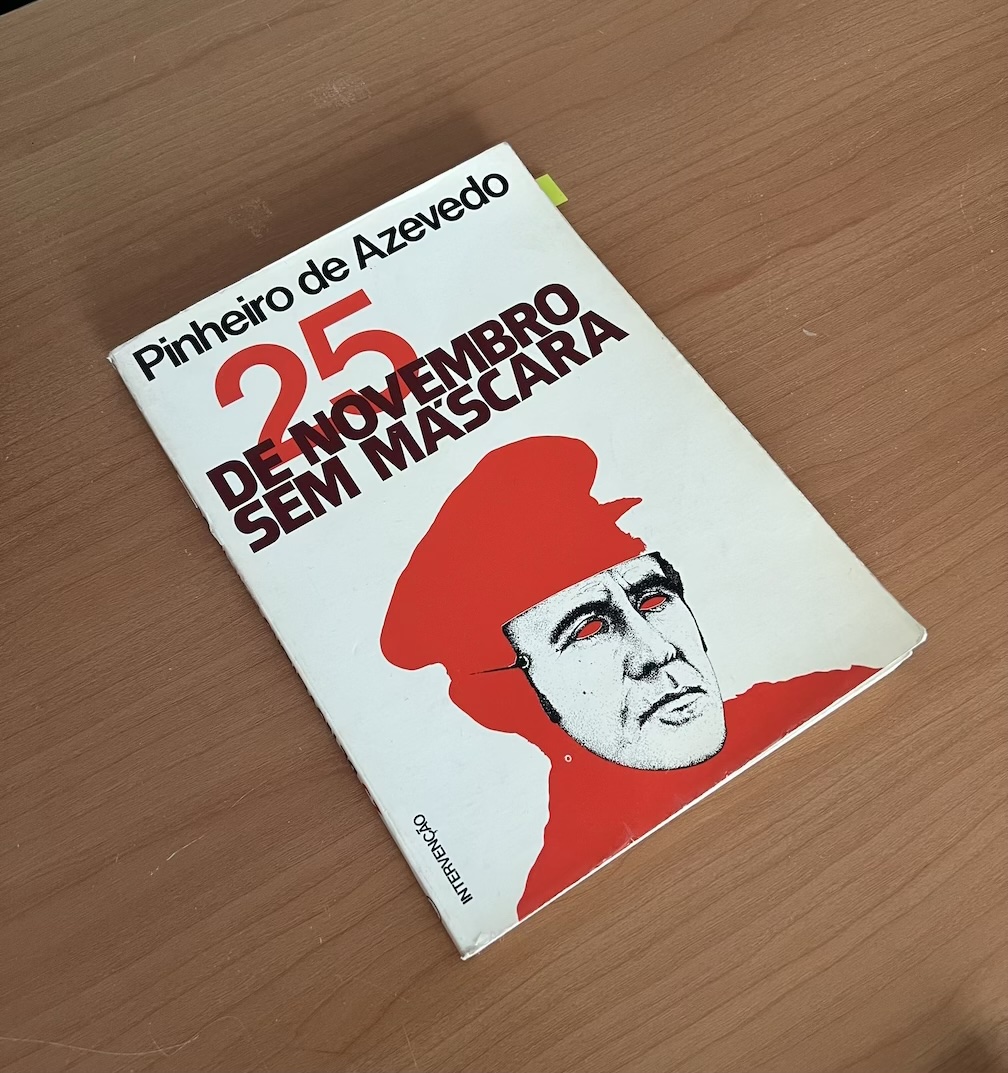
<p>Em 1979, uns escassos 5 anos depois do 25 de Abril de 1974, o Alm. Pinheiro de Azevedo publicou o 25 de Novembro sem Máscara.</p>

<p>Não obstante não ser um figura histórica particularmente conhecida, Pinheiro de Azevedo esteve envolvido em praticamente todo o período revolucionário. Aderiu ao MFA e participou no 25 de Abril. Foi membro da Junta de Salvação Nacional e do Concelho da Revolução. Tomou posse como Primeiro-Ministro no VI Governo Provisório, cargo este que exercia quando se deu o 25 de Novembro.</p>

<p>O episódio mais conhecido em que esteve envolvido foi o do Cerco à Assembleia Constituinte,<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> quando por volta de 100 000 manifestantes sequestraram o Governo e os Deputados. Terminado o cerco, o Almirante foi entrevistado e aí declarou, com uma postura praticamente casual, as palavras que o imortalizaram como o <em>Almirante sem Medo</em>:</p>

<blockquote>
  <p>Estou farto de brincadeiras (…) Fui sequestrado. Já duas vezes. Já chega, não gosto de ser sequestrado. É uma coisa que me chateia.<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup></p>
</blockquote>

<p>Tendo aderido ao MFA no espírito do Programa<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup> por este proposto, o Almirante — um moderado — manifesta-se consistentemente contra todos os exageros revolucionários e o primar da extrema-esquerda que caracterizou o período entre o 25 de Abril e o 25 de Novembro.</p>

<p>Critica a forma como a descolonização é feita, entregando o ultramar a facções satélites da União Soviética e impedindo a auto-determinação dos habitantes — o que culminou na crise dos retornados. Mostra-se contra as expropriações e nacionalizações praticadas com autorização do Governo, ambições colectivistas estas que destruíram grande parte do poder económico. É crítico da aprovação da Constituição de 1976, de inspiração soviética.</p>

<p>Mas é o 25 de Novembro que o livro, principalmente, trata. O Almirante descreve o evento como existindo sob uma “máscara hipócrita do regresso à pureza do 25 de Abril”. Interpretação esta que, hipócrita ou não, corresponde hoje, 45 anos depois, à norma.</p>

<p>Afirma que o 25 de Novembro não serviu para por termo aos excessos revolucionários mas que, pelo contrário, serviu para os legitimar.</p>

<p>A revolução já estava feita, só faltava garantir que não seria desfeita. A Constituição de 1976, escrita durante o período de domínio comunista, foi aprovada. As conquistas comunistas foram legitimadas. O 25 de Novembro derrotou o Partido Comunista e desmobilizou a frente anti-comunista que se estava a formar. O PC perdeu força mas o seu trabalho já estava feito: a descolonização, as expropriações, a Constituição.</p>

<p>Num tom mais conspiratório, alega que o 25 de Novembro terá sido executado de acordo com um plano pré-estabelecido do PC que visava eliminar facções políticas à sua esquerda. Mais ainda, acusa que o Presidente Ramalho Eanes terá sido escolhido pelas chefias do PC para por este plano em marcha – porque, alegadamente, teria simpatias comunistas.</p>

<p>Verdade ou não, o livro relata uma perspectiva diferente sobre a revolução, redigida por um dos seus intervenientes. Só por isto, merece ser lido.</p>

<p>Anotei uma passagem do livro que achei particularmente lúcida:</p>

<blockquote>
  <p>Posição típica, aliás, dos homens de esquerda: os princípios estão sempre certos, são sempre certos; na forma de actuar é que podem haver erros e a acção é que é susceptível de correcções.</p>
</blockquote>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p><a href="https://app.parlamento.pt/comunicar/Artigo.aspx?ID=559&amp;IDSubTitulo=340">https://app.parlamento.pt/comunicar/Artigo.aspx?ID=559&amp;IDSubTitulo=340</a> <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p><a href="https://www.youtube.com/watch?v=gqOOla0PS8M">https://www.youtube.com/watch?v=gqOOla0PS8M</a> <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p><a href="https://www.arquivo.presidencia.pt/viewer?id=7281&amp;FileID=315367&amp;recordType=Description">https://www.arquivo.presidencia.pt/viewer?id=7281&amp;FileID=315367&amp;recordType=Description</a> <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="literature" /><category term="policy" /><summary type="html"><![CDATA[Software engineer. Built healthcare and recruitment software. Interested in finance, economics and policy.]]></summary></entry><entry xml:lang="pt-PT"><title type="html">Review: As Causas do Atraso Português</title><link href="https://0x1.pt/2024/05/22/review-as-causas-do-atraso-portugues/" rel="alternate" type="text/html" title="Review: As Causas do Atraso Português" /><published>2024-05-22T00:00:00+00:00</published><updated>2024-05-22T00:00:00+00:00</updated><id>https://0x1.pt/2024/05/22/review-as-causas-do-atraso-portugues</id><content type="html" xml:base="https://0x1.pt/2024/05/22/review-as-causas-do-atraso-portugues/"><![CDATA[<p><img src="/assets/review-as-causas-do-atraso-portugues/capa.png" alt="As Causas do Atraso Português - Capa" class="mx-auto" width="400" height="453" /></p>

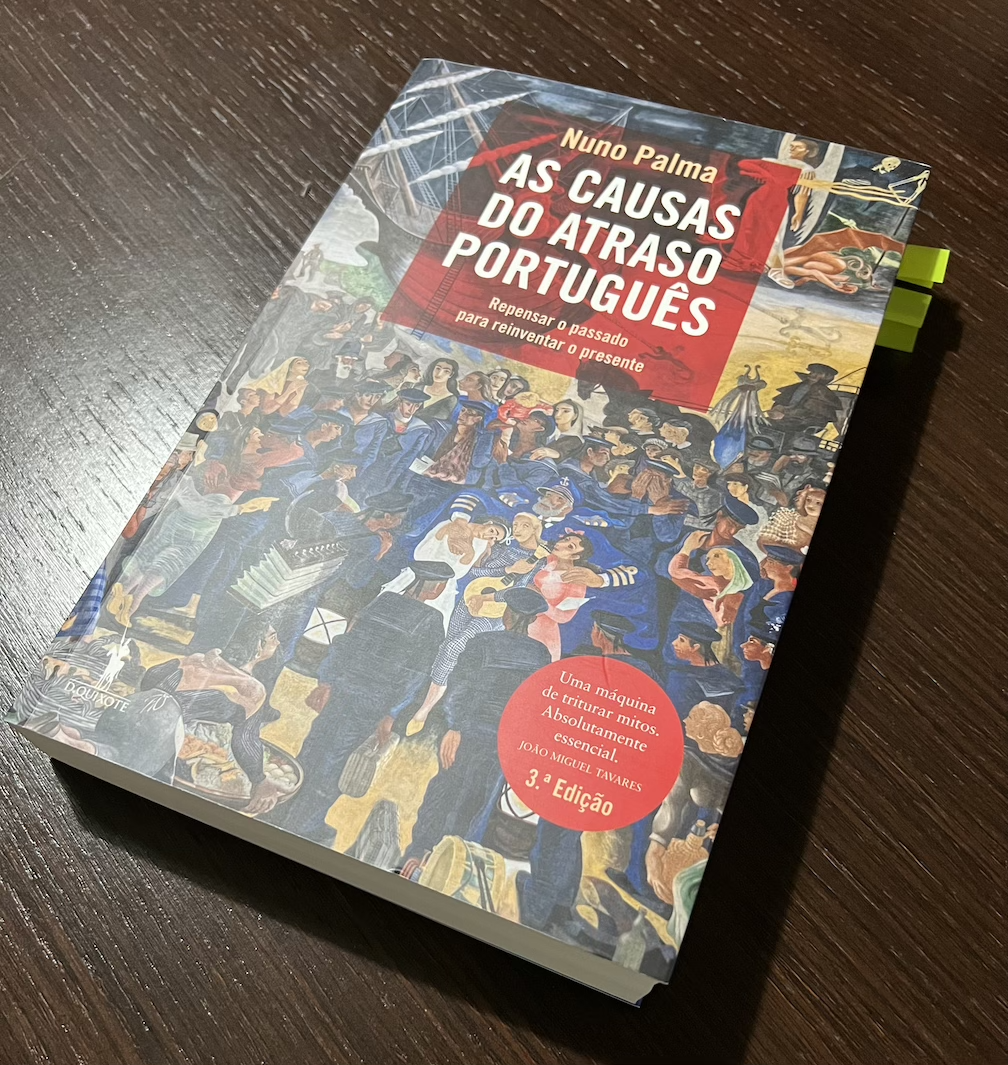
<p>O Professor Nuno Palma, da Universidade de Manchester, escreve-nos uma versão da história económica portuguesa mais moderada, preocupada em desfazer noções e interpretações sobre o nosso passado que não são correctas.</p>

<p>Nas palavras de João Miguel Tavares, o livro é “uma máquina de triturar mitos.” Sintetizo aqui alguns daqueles que mais me disseram.</p>

<p>O primeiro, sobre o Marquês de Pombal. Um homem tido, por norma, como progressista, à frente do seu tempo e um ditador iluminado. Este deu, no entanto, início ao atraso educativo do país ao expulsar os jesuítas – que regiam a maior parte das escolas, na altura – sem implementar um sistema de ensino alternativo. Atraso educativo este do qual, ainda hoje, não recuperámos.</p>

<p>Seguindo para a Primeira República, tida como o início da nossa democracia e violentamente interrompida pelo reaccionarismo do Estado Novo. O autor descreve que estes foram anos perdidos, de regressão, onde as poucas reformas legisladas ficaram, apenas, no papel. Curiosamente, apesar de haverem eleições, haviam muito poucos eleitores elegíveis já que os analfabetos não podiam votar. Estes formavam 70% da população em 1911.</p>

<p>O capítulo sobre o Estado Novo é o mais polémico. O autor destaca que o número de analfabetos que apenas descera de 70% para 62% na Primeira República foi reduzido para 42% em 1950. Que a industrialização e convergência económica com a Europa Ocidental foram iniciadas em 1950 e que o rendimento média por pessoa subiu “de forma vertiginosa” multiplicando-se por cinco de 1926 a 1974. Que a percentagem de indivíduos que sofriam deficiências de crescimento (por causa da mal-nutrição e falta de cuidados de saúde) desceu, drasticamente, nos anos da ditadura.</p>

<p>Citando Nuno Palma, “qualquer sucesso a nível do desenvolvimento económico e dos efeitos favoráveis para o bem-estar das populações não justifica o amordaçar da liberdade.” O que é inquestionável. Igualmente inquestionável é que participar em revisionismos históricos é profundamente anti-democrático. Devemos olhar, objectivamente, para os sucessos e insucessos do Estado Novo e ambicionarmos, sempre, fazer melhor em democracia.</p>

<p>Para finalizar, destaco um último ponto – o que achei mais interessante – que é a análise que o autor faz das repercussões negativas do pendor socialista do 25 de Abril. O primeiro destes sendo a primazia, na Assembleia da República, de partidos que propõem sistemas económicos desadequados e que, dogmaticamente, rejeitam ideias alternativas. Outro, a carga negativa atribuída a termos como “liberal”, “capitalista”, “conservador” e “de direita” que são desprovidos de significado e usados como insultos para inviabilizar partidos, pessoas e ideias. Tudo isto em prejuízo das pessoas.<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<p>O livro é extremamente legível e não há qualquer indício de academiquês. Os únicos aspectos negativos que destaco são o meta discurso, por vezes, excessivo e uma crítica demasiado constante ao status-quo da história económica e aos os seus autores – sendo, no entanto, esta crítica perfeitamente legítima.</p>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Parece-me que há uma luz ao fundo no túnel, no entanto, e acho que aparecimento de partidos como a Iniciativa Liberal é um indício desta mudança. Há 10 ou 20 anos, um partido com esta ideologia estaria condenado ao insucesso no sufrágio. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="literature" /><category term="policy" /><summary type="html"><![CDATA[Software engineer. Built healthcare and recruitment software. Interested in finance, economics and policy.]]></summary></entry><entry xml:lang="pt-PT"><title type="html">Fundos de Pensões e PPR/OICVM</title><link href="https://0x1.pt/2024/02/25/fundos-de-pensoes-e-ppr-oicvm/" rel="alternate" type="text/html" title="Fundos de Pensões e PPR/OICVM" /><published>2024-02-25T00:00:00+00:00</published><updated>2024-02-25T00:00:00+00:00</updated><id>https://0x1.pt/2024/02/25/fundos-de-pensoes-e-ppr-oicvm</id><content type="html" xml:base="https://0x1.pt/2024/02/25/fundos-de-pensoes-e-ppr-oicvm/"><![CDATA[<p>Os Planos Poupança Reforma (PPR) são um dos investimentos de excelência a longo prazo, em Portugal, dadas as suas vantagens fiscais significativas. Existem imensos PPR à escolha e inúmeras análises destes. Não serão, no entanto, muitos os que saberão que, na verdade, a designação casual “PPR” não se refere a um mas a dois tipos de produtos diferentes: os <strong>Fundos de Pensões</strong> e os <strong>PPR/OICVM.</strong></p>

<h3 id="fundos-de-pensões">Fundos de Pensões</h3>

<ul>
  <li>Regulados pela Autoridade de Supervisão de Seguros e Fundos de Pensões (ASF).</li>
  <li>Geridos por sociedades gestoras de fundos de pensões.</li>
  <li>Só é permitido o resgate atingida a reforma ou os 60 anos de idade.<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></li>
  <li>O resgate é feito através de pensões com periodicidade mensal. Se previsto no plano de pensões, pode ser pedido o reembolso de um terço do capital na primeira mensalidade.</li>
  <li>Taxa sobre as mais valias de 8%, no resgate.</li>
  <li>Não existe restrição no tipo dos activos constituintes do fundo.</li>
  <li>Não é possível transferir o capital para um PPR/OICVM.</li>
</ul>

<p>Resumindo, estes fundos são exclusivamente orientados para gerar poupanças para a reforma, de tal forma que nem pode ser pedido o resgate fora das condições previstas na lei.<sup id="fnref:1:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></p>

<h3 id="planos-poupança-reformaorganismos-de-investimento-colectivo-em-valores-mobiliários-pproicvm">Planos Poupança Reforma/Organismos de Investimento Colectivo em Valores Mobiliários (PPR/OICVM)</h3>

<ul>
  <li>Regulados pela Comissão de Mercado de Valores Mobiliários (CMVM).</li>
  <li>Geridos por entidades habilitadas a gerir organismos de investimento colectivo em valores mobiliários, entre outras.</li>
  <li>Resgate permitido em qualquer altura.</li>
  <li>A totalidade do capital é reembolsada de uma só vez.</li>
  <li>Taxa sobre as mais valias de 21.5% para subscrições com menos de 5 anos, 17.2% para subscrições com mais de 5 e menos de 8 anos e 8.6% acima de 8 anos. Taxa de 8% se atingida a reforma ou os 60 anos de idade.<sup id="fnref:1:2"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup></li>
  <li>O fundo não pode investir em activos imobiliários.</li>
  <li>Não é possível transferir o capital para um fundo de pensões.</li>
</ul>

<p>Resumindo, o PPR/OICVM acaba por ser um fundo de investimento igual aos outros com a vantagem de ter um imposto sobre as mais valias significativamente inferior ao normal de 28%, em determinadas condições.</p>

<h3 id="como-é-que-consigo-saber-se-o-meu-ppr-é-um-fundo-de-pensões-ou-um-pproicvm">Como é que consigo saber se o meu “PPR” é um fundo de pensões ou um PPR/OICVM?</h3>

<p>A forma mais simples é ir à <a href="https://www.asf.com.pt/autoriza%C3%A7%C3%B5es-e-registos/fundos-de-pens%C3%B5es/entidades-autorizadas">página de pesquisa</a> de fundos de pensões no site da ASF e pesquisar pelo nome do “PPR”.</p>

<p>Em alternativa, a lei requer que a empresa que gere um fundo de pensões inclua a expressão “Sociedade Gestora de Fundos de Pensões” no nome e que um PPR/OICVM inclua, na denominação do fundo, a expressão “PPR/OICVM”.</p>

<p>Por exemplo, no <a href="https://stoik.pt/s/Regulamento-Gestao-PPR-SGF-Stoik.pdf">regulamento de gestão</a> do PPR SGF Stoik – que, confusamente, tem “PPR” no nome – pode-se confirmar que a entidade gestora se chama “Golden-SGF, Sociedade Gestora de Fundos de Pensões, S.A.”</p>

<p>Já no <a href="https://drive.google.com/file/d/1R4V5DA1GOa-MY7jEnL0GzJfHVYD0vDTR/view">documento informativo</a> do Save &amp; Grow é possível verificar que o denominação do fundo é “Save &amp; Grow PPR/OICVM - Fundo de Investimento Mobiliário Aberto de Acções de Poupança Reforma.”</p>

<h3 id="por-qual-tipo-de-ppr-devo-optar">Por qual tipo de PPR devo optar?</h3>

<p>Há determinados artigos a opinar ou que os fundos de pensões ou os PPR/OICVM são melhores porque uns ou outros têm, em média, rentabilidades superiores ou comissões mais baixas. Mas isto, como é evidente nos pontos acima indicados, não está relacionado com a <em>framework</em> legal em que o fundo opera mas apenas na qualidade da gestão do mesmo.</p>

<p>Dito isto, se o objectivo é exclusivamente investir para a reforma, praticamente que não há diferenças. Os PPR/OICVM têm uma pequena vantagem porque permitem o resgate de todo o capital de uma só vez.</p>

<p>Se o objectivo é investir mas, possivelmente, optar por um resgate mais cedo, então os PPR/OICVM são claramente o fundo mais vantajoso.</p>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Excluindo aqui situações excepcionais em que o resgate é possível como desemprego de longa duração, doença grave, incapacidade permanente para o trabalho, entre outras. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:1:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a> <a href="#fnref:1:2" class="reversefootnote" role="doc-backlink">&#8617;<sup>3</sup></a></p>
    </li>
  </ol>
</div>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="finance" /><summary type="html"><![CDATA[Os Planos Poupança Reforma (PPR) são um dos investimentos de excelência a longo prazo, em Portugal, dadas as suas vantagens fiscais significativas. Existem imensos PPR à escolha e inúmeras análises destes. Não serão, no entanto, muitos os que saberão que, na verdade, a designação casual “PPR” não se refere a um mas a dois tipos de produtos diferentes: os Fundos de Pensões e os PPR/OICVM.]]></summary></entry><entry><title type="html">Review: Politics is for Power</title><link href="https://0x1.pt/2024/01/03/review-politics-is-for-power/" rel="alternate" type="text/html" title="Review: Politics is for Power" /><published>2024-01-03T00:00:00+00:00</published><updated>2024-01-03T00:00:00+00:00</updated><id>https://0x1.pt/2024/01/03/review-politics-is-for-power</id><content type="html" xml:base="https://0x1.pt/2024/01/03/review-politics-is-for-power/"><![CDATA[<p><img src="/assets/review-politics-is-for-power/cover.jpg" alt="Politics is for Power - Book Cover" class="mx-auto" width="300" height="453" /></p>

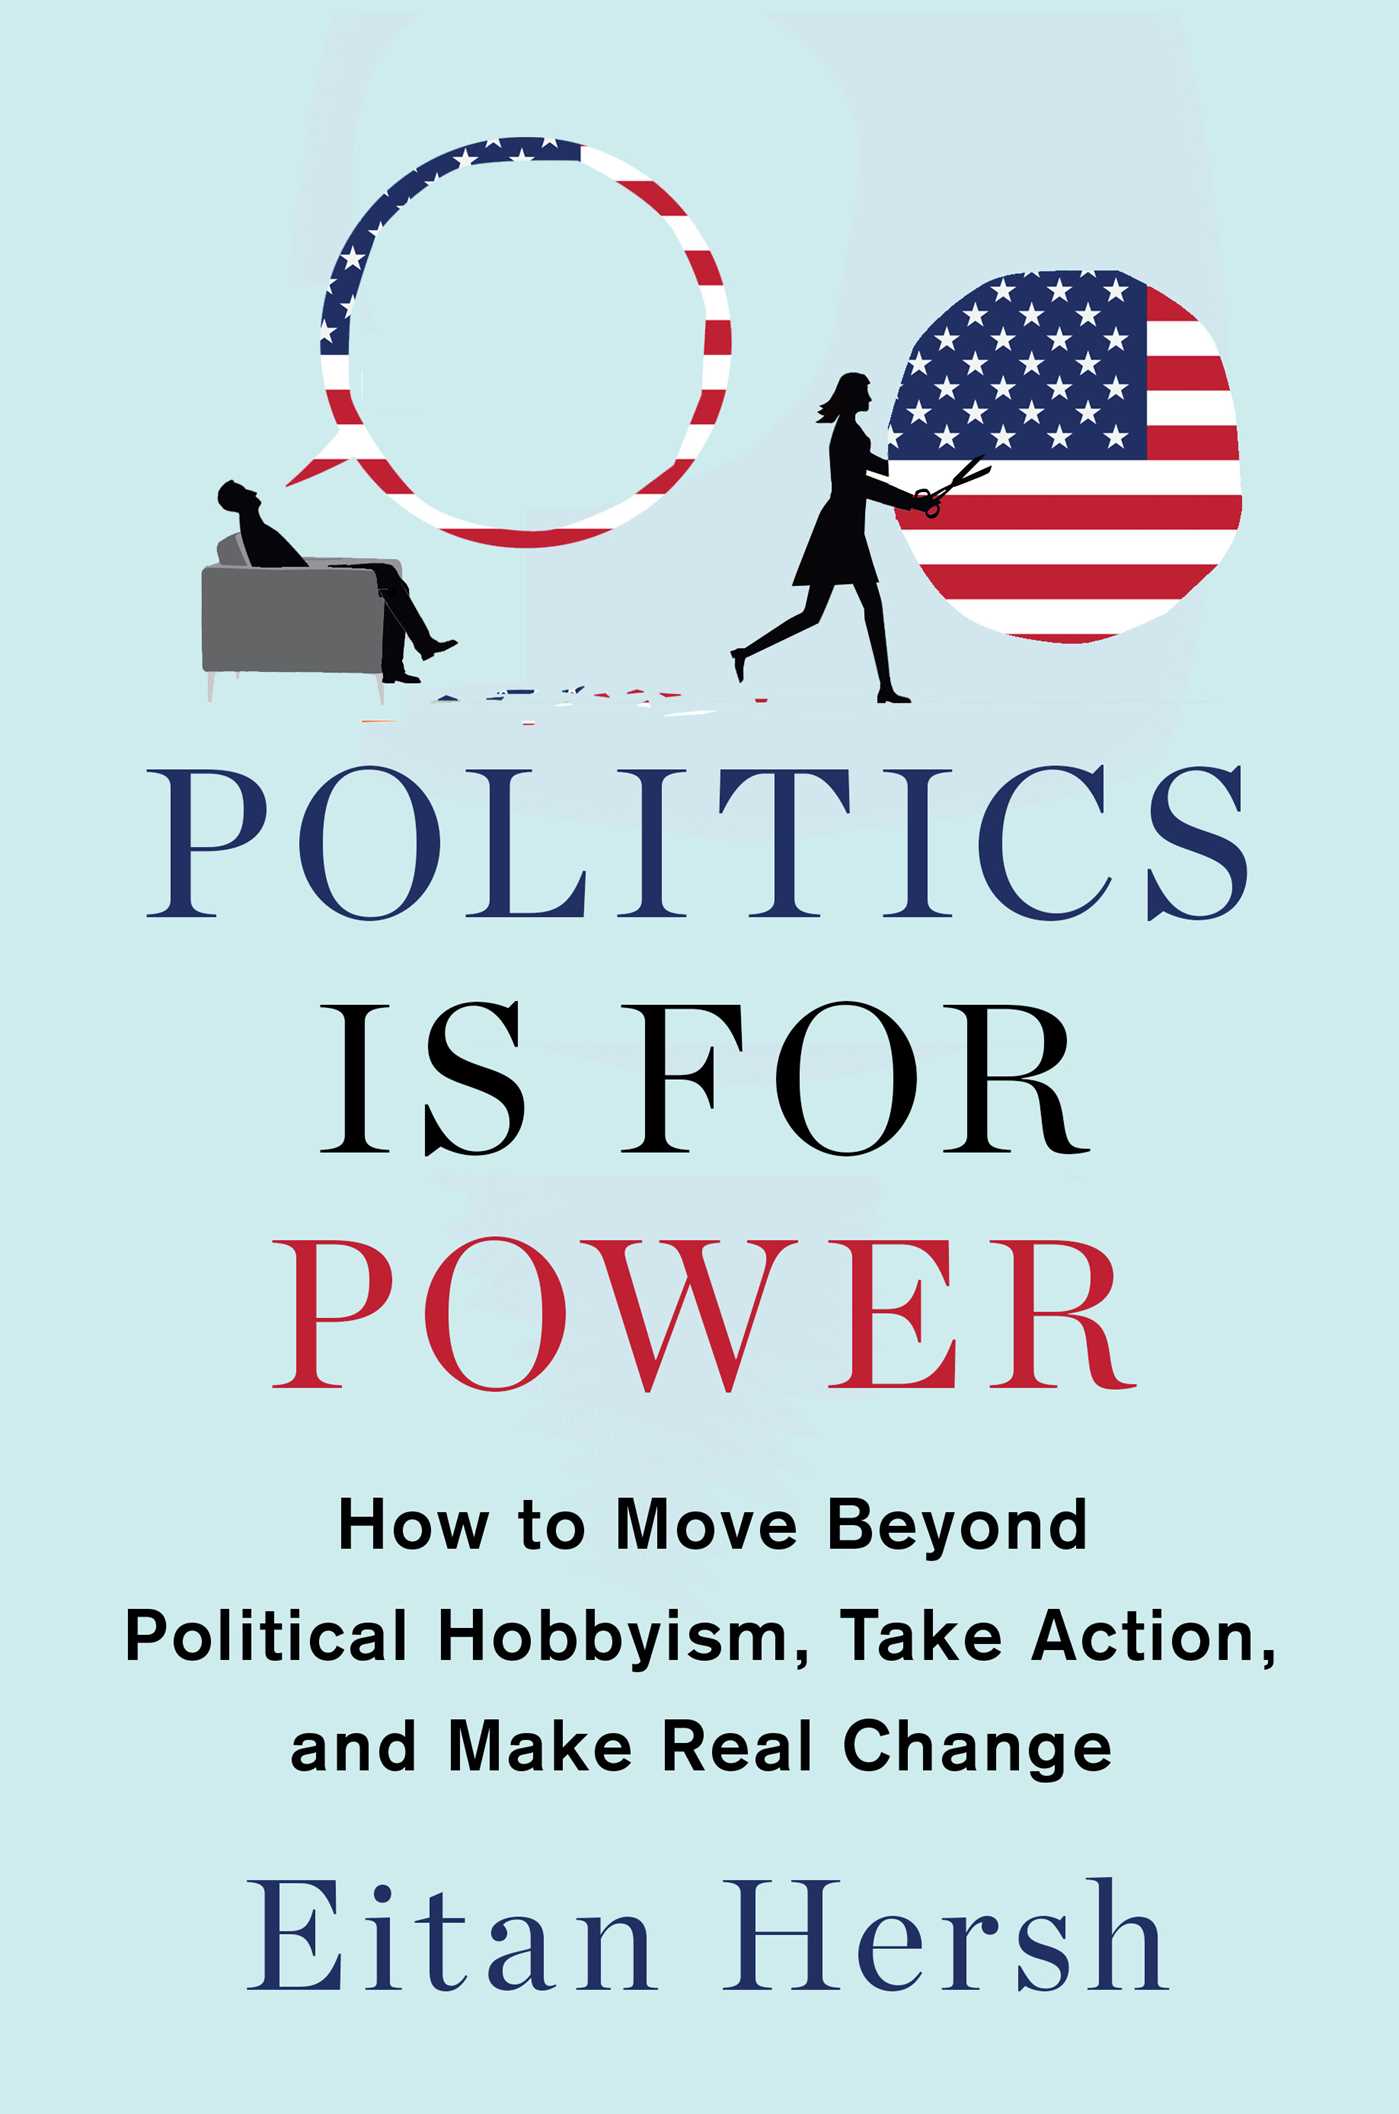
<p>This book made me think about what it really means to participate in politics. Not for the ones in power, but for the rest of us.</p>

<p>Eitan Hersh establishes a difference between “political hobbyism” and doing real politics.</p>

<p>Political hobbyism is what most of us do. At cafés, dinner tables and online we have really long discussions about the latest political scandals or whether a certain policy suggested by a certain party really, really fits into the party’s ideology and how we really, really don’t like that ideology. The author affirms this isn’t really doing politics because, to sum up, it achieves absolutely nothing — which I agree with.</p>

<p>How many times have you changed the way you intended to vote because a friend made a passionate and knowledgeable speech about the party or candidate they support?</p>

<p>Real politics is about acquiring power. It’s about multiplying your vote. It’s about picking a party that you think will benefit everyone the most — even if you don’t agree with everything they do — and going door to door and making it a point to help your neighbors and, as such, garner their votes.</p>

<p>This is called “deep canvassing”. It, more or less, means establishing a more personal relationship with whoever you’re trying to convince to vote your way. This is done by making the conversation personal and asking the voter for the issues they’d like to have solved instead of reciting a party-approved text from memory. The point is to establish empathy and, therefore, convince the voter to vote your way without explicitly telling them to do so because they can see that you care. Weirdly, I can’t figure out if this is actually a better, more humane and useful way to garner votes or just straight up manipulation.</p>

<p>Even more controversial is the idea that “power is derived from serving others”. On itself, this seems like a an extraordinarily democratic motto. What is really means is that providing direct services to voters will make them support you. So, you’d make health counseling, financial clinics, kindergarten and other services available to voters and have them vote for you without explicitly telling them to as you’re improving their lives.</p>

<p>Once again — on one hand, this feels like a much better way of doing politics as you’d have party cash being funneled into real services being made available to people instead of political billboards, television ads and empty speeches. On the other hand, it almost feels like paying people for their vote. “Vote for the X party and have free kindergarten and a 20% gym discount coupon.”</p>

<p>Despite the heavy topic, I’d say the book is very easy to read and would recommend it to anyone interested in politics. While the book portrays US politics, I think it applies equally as well to any established democracy.</p>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="literature" /><category term="policy" /><summary type="html"><![CDATA[Software engineer. Built healthcare and recruitment software. Interested in finance, economics and policy.]]></summary></entry><entry><title type="html">Trying out C++20’s modules with Clang and Make</title><link href="https://0x1.pt/2023/10/15/trying-out-c++20s-modules-with-clang-and-make/" rel="alternate" type="text/html" title="Trying out C++20’s modules with Clang and Make" /><published>2023-10-15T00:00:00+00:00</published><updated>2023-10-15T00:00:00+00:00</updated><id>https://0x1.pt/2023/10/15/trying-out-c++20s-modules-with-clang-and-make</id><content type="html" xml:base="https://0x1.pt/2023/10/15/trying-out-c++20s-modules-with-clang-and-make/"><![CDATA[<p><em>Edit (26/01/2024): As some people have pointed out <a href="https://news.ycombinator.com/item?id=37889631">on Hacker News</a>, the Makefile I show below fails to properly track dependencies in several scenarios. Lexi Winter has <a href="https://git.sr.ht/~lw/cxx-modules-bmake">a repository on SourceHut</a> showing how to implement correct dependency tracking with BSD Make.</em></p>

<p>Header files are a relic from the past. No modern programming language has an equivalent concept.</p>

<p>As far as I know, header files came to be because when C was built disk space was at a prime and storing libraries with their full source code would be expensive. Header files included just the necessary to be able to call into the library while being considerably smaller.</p>

<p>C++20’s modules are C++’s attempt to do away with header files and implement traditional modules like most programming languages. Both MSVC and GCC implement modules, at least partially, but I usually reach for Clang so let’s give it a try.</p>

<p>Here’s some annotated source code for a module.</p>

<pre><code class="language-c++"><span class="hl-c">// mod1.ccm - A module. Notice the extension.</span>

<span class="hl-c">// Needed because we're importing headers in this module.</span>
<span class="hl-k">module</span>;

<span class="hl-k">#include</span> &lt;iostream&gt;

<span class="hl-c">// Export the module with a name that matches the filename.</span>
<span class="hl-k">export</span> <span class="hl-k">module</span> mod1;

<span class="hl-c">// Modules are orthogonal to namespaces.</span>
<span class="hl-k">namespace</span> demo {

<span class="hl-c">// We're exporting this class with the 'export' keyword.</span>
<span class="hl-k">export</span> <span class="hl-k">class</span> Printer {
<span class="hl-k">public</span>:
  <span class="hl-t">void</span> Print() { std::cout &lt;&lt; <span class="hl-s">"Hi from the module\n"</span>; }
};

}
</code></pre>

<p>And here’s a regular source file that calls the module.</p>

<pre><code class="language-c++"><span class="hl-c">// main.cc - A regular C++ file</span>

<span class="hl-c">// And here we're importing the module we defined above.</span>
<span class="hl-k">import</span> mod1;

<span class="hl-t">auto</span> main() -&gt; <span class="hl-t">int</span> {
  demo::Printer printer;
  printer.Print();
  <span class="hl-k">return</span> <span class="hl-n">0</span>;
}
</code></pre>

<p>Finally, a <code>Makefile</code> to pull both files together.</p>

<pre><code class="language-makefile">CXX := clang++

CXXFLAGS := -std=c++20 -fprebuilt-module-path=.

MODS := mod1.ccm
SRCS := main.cc
OBJS := <span class="hl-v">$(MODS:.ccm=.o)</span> <span class="hl-v">$(SRCS:.cc=.o)</span>

exe: <span class="hl-v">$(OBJS)</span>
	<span class="hl-v">$(CXX)</span> -o <span class="hl-v">$@</span> <span class="hl-v">$^</span>

%.o: %.ccm
	<span class="hl-v">$(CXX)</span> <span class="hl-v">$(CXXFLAGS)</span> -fmodule-output -c <span class="hl-v">$&lt;</span> -o <span class="hl-v">$@</span>

%.o: %.cc
	<span class="hl-v">$(CXX)</span> <span class="hl-v">$(CXXFLAGS)</span> -c <span class="hl-v">$&lt;</span> -o <span class="hl-v">$@</span>
</code></pre>

<p>And now let’s compile and run.</p>

<pre><code class="language-plaintext">$ make
clang++ -std=c++20 -fprebuilt-module-path=. -fmodule-output -c mod1.ccm -o mod1.o
clang++ -std=c++20 -fprebuilt-module-path=. -c main.cc -o main.o
clang++ -o exe mod1.o main.o
$ ./exe
Hi from the module
</code></pre>

<p>We passed a couple of unfamiliar options to Clang.</p>

<p>The <code>-fmodule-output</code> option makes it generate a “Built Module Interface” as part of the compilation. This is the <code>*.pcm</code> file you now see in the build directory.</p>

<p>The <code>-fprebuilt-module-path=.</code> option passes the path to the directory that holds the <code>*.pcm</code> files.</p>

<hr />

<p>Not having to duplicate a bunch of code between header and implementation files is certainly a productivity boost. And not having to deal with <code>#pragma once</code> and include guards is very nice.</p>

<p>The compilation time for modules seems to be worse that regular translation units. This is to be expected as it’s now generating two files. I do wonder why there’s a need to generate <code>.pcm</code> files. Couldn’t their content be added to the object file in a backwards compatible manner? Still, I wouldn’t be surprised that this improves significantly as this process gets optimized.</p>

<p>What I think is a bit weird is that we now have modules and namespaces. I sort of expected that we wouldn’t need namespace anymore but it’s not the case. Modules really only handle the “import” part and not the “name disambiguation” part. It would be better if it worked more like Python’s modules.</p>

<p>Another weird part is that the standard library is currently lacking modules so you need to keep importing headers. MSVC has support for doing <code>import std.core</code> but it’s marked as experimental and doesn’t seem to work on Clang. General support for this is bound to come later.</p>

<p>Overall, despite these weird bits, C++’s modules are certainly an improvement.</p>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="engineering" /><category term="c++" /><summary type="html"><![CDATA[Edit (26/01/2024): As some people have pointed out on Hacker News, the Makefile I show below fails to properly track dependencies in several scenarios. Lexi Winter has a repository on SourceHut showing how to implement correct dependency tracking with BSD Make.]]></summary></entry><entry><title type="html">Subscriber Only: A Technical Post Mortem</title><link href="https://0x1.pt/2023/08/08/subscriber-only-a-technical-post-mortem/" rel="alternate" type="text/html" title="Subscriber Only: A Technical Post Mortem" /><published>2023-08-08T00:00:00+00:00</published><updated>2023-08-08T00:00:00+00:00</updated><id>https://0x1.pt/2023/08/08/subscriber-only-a-technical-post-mortem</id><content type="html" xml:base="https://0x1.pt/2023/08/08/subscriber-only-a-technical-post-mortem/"><![CDATA[<p>Around 3 months ago, <a href="/2023/06/10/launching-subscriber-only/">I launched a service called Subscriber Only</a>. Due to lack of users, I’m shutting it down. Such is life.</p>

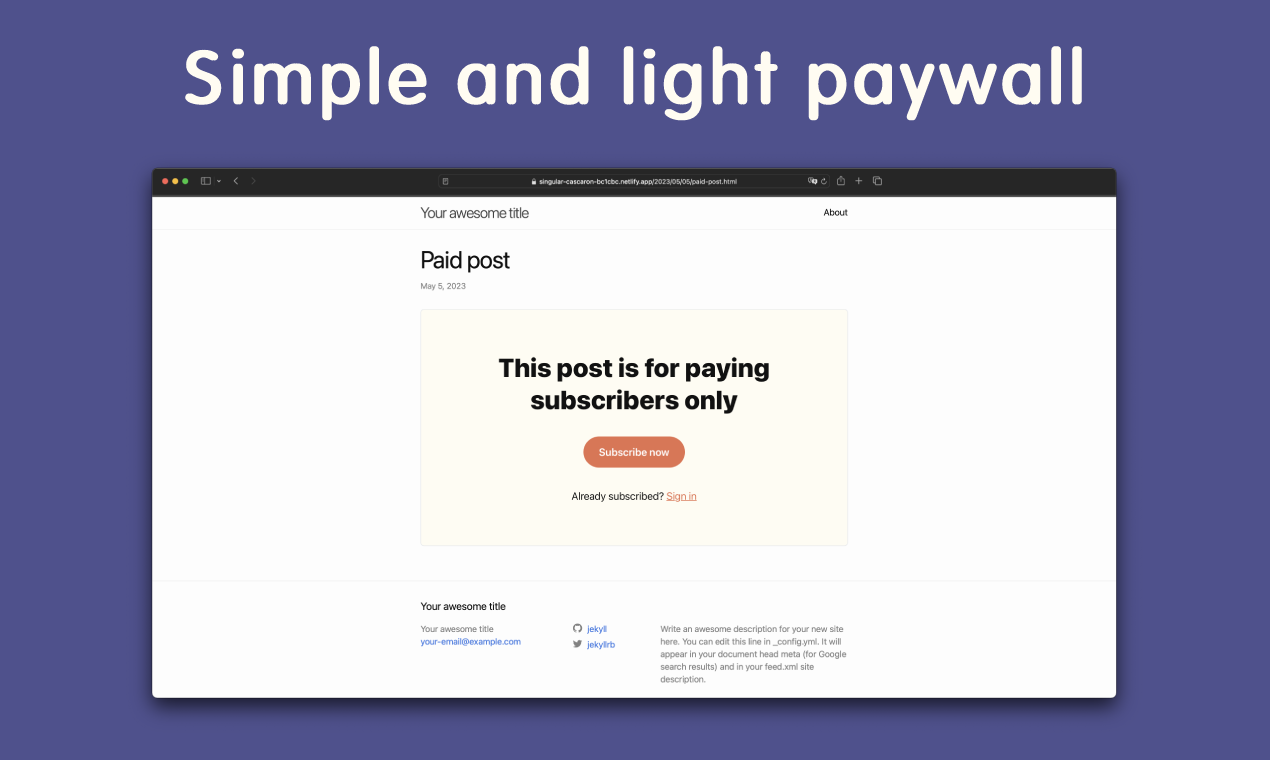
<p>I’m making all of the code I wrote public. Get it while it’s fresh from GitHub.</p>

<p><a href="https://github.com/subscriber-only/subscriber-only">https://github.com/subscriber-only/subscriber-only</a></p>

<p>Here’s a couple of interesting things I did and learned while working on it.</p>

<h2 id="overview">Overview</h2>

<p>Subscriber Only (SO) allows writers to tag certain posts on their Jekyll blog as gated/premium/paid and then figures out if the reader should or should not have access to the said post. It handles all the machinery needed to maintain subscriptions. It’s kind of like Substack, Patreon or OnlyFans.</p>

<p>It poses a unique challenge, when compared to the mention sites, because the content is served from the writer’s own hosting on their own domain and not a centralized place (sort-of).</p>

<p>Here’s how I went about solving this.</p>

<p>First, there’s a <a href="https://github.com/subscriber-only/jekyll-subscriber_only">Jekyll plugin</a> that hooks into the site’s build step. Every post that’s tagged with <code>subscriber_only</code> gets its content stripped and uploaded to SO’s backend.</p>

<p>Second, there’s an “agent” script that gets added to the post’s <code>&lt;head&gt;</code> – kind of like Google Analytics. This script figures out if the reader is subscribed to the site they’re currently reading and shows them either the content or a paywall with instructions on how to login or subscribe.</p>

<p>This script is, probably, the most interesting part of the whole project. Check out <a href="https://github.com/subscriber-only/subscriber-only/blob/main/public/so.js">so.js</a></p>

<p>The logic that’s associated with this script turned out to be much more complicated than I imagined. Starting with…</p>

<h2 id="cors">CORS</h2>

<p>It turns out that if you want to issue a request from <code>your-jekyll-site.com</code> to <code>app.subscriber-only.com</code> that you can’t just do it. Even if the script that’s issuing the requests is at <code>app.subscriber-only.com/so.js</code></p>

<p>SO must tell the browser which origins – domains – are allowed to issue requests to it and even which headers it accepts.</p>

<p>There’s a pretty nice gem called <a href="https://github.com/cyu/rack-cors">rack-cors</a> that let’s you configure this in a declarative way. You can find SO’s configuration in the <a href="https://github.com/subscriber-only/subscriber-only/blob/main/config/initializers/cors.rb">cors.rb initializer.</a></p>

<h2 id="poor-mans-react">Poor man’s React</h2>

<p>Another challenge was building the paywall that gets shown to the reader if they’re not subscribed.</p>

<p><img src="/assets/subscriber-only/PH_2.png" alt="Screenshot of Subscriber Only's paywall on a default Jekyll Site" width="1270" height="760" /></p>

<p>Rendering the paywall needed to not require much code as it would bloat <code>so.js</code> which would delay the script’s download and make the user experience worse. This ruled out large UI libraries like React and EJS.</p>

<p>It also needed to be better than just concatenating strings together to form some HTML because I care about developer ergonomics.</p>

<p>I settled on a <code>createElement()</code> function that looks <a href="https://react.dev/reference/react/createElement">very much like React’s</a>. I found a version of this function on Hacker News but can’t find the link.<sup id="fnref:1"><a href="#fn:1" class="footnote" rel="footnote" role="doc-noteref">1</a></sup> Here’s how it looks.</p>

<pre><code class="language-js"><span class="hl-k">function</span> createElement(type = <span class="hl-s">"div"</span>, props = {}, children = []) {
  <span class="hl-k">if</span> (props?.constructor !== Object) {
    children = props;
    props = {};
  }
  <span class="hl-k">if</span> (!Array.isArray(children)) children = [children];
  <span class="hl-k">const</span> el = document.createElement(type);
  Object.assign(el, props);
  Object.assign(el.style, props.style || {});
  el.append(...children.filter(Boolean));
  <span class="hl-k">return</span> el;
}
</code></pre>

<p>It takes an element type, an object of props which must map to the properties the element has and an array of children. Then it returns the element which can be placed on the DOM.</p>

<p>Here’s the function in action. It’s being used to build some placeholder sentences that get displayed while the script is running background operations.</p>

<pre><code class="language-js"><span class="hl-k">const</span> e = createElement;

<span class="hl-k">function</span> PlaceholderSentence(width) {
  <span class="hl-k">return</span> e(<span class="hl-s">"span"</span>, { style: {
    display: <span class="hl-s">"inline-block"</span>,
    minHeight: <span class="hl-s">"1em"</span>,
    verticalAlign: <span class="hl-s">"middle"</span>,
    cursor: <span class="hl-s">"wait"</span>,
    backgroundColor: <span class="hl-s">"currentColor"</span>,
    opacity: <span class="hl-n">.5</span>,
    width,
  }});
}

<span class="hl-k">function</span> PlaceholderRow(widths) {
  <span class="hl-k">const</span> style = { display: <span class="hl-s">"flex"</span>, gap: <span class="hl-s">"8px"</span> };
  <span class="hl-k">return</span> e(<span class="hl-s">"div"</span>, { style }, widths.map(PlaceholderSentence));
}

<span class="hl-k">function</span> PlaceholderText() {
  <span class="hl-k">const</span> style = {
    display: <span class="hl-s">"flex"</span>,
    flexDirection: <span class="hl-s">"column"</span>,
    gap: <span class="hl-s">"8px"</span>
  };

  <span class="hl-k">return</span> e(<span class="hl-s">"div"</span>, { style }, [
    PlaceholderRow([<span class="hl-s">"30%"</span>, <span class="hl-s">"70%"</span>]),
    PlaceholderRow([<span class="hl-s">"10%"</span>, <span class="hl-s">"50%"</span>, <span class="hl-s">"40%"</span>]),
    PlaceholderRow([<span class="hl-s">"40%"</span>, <span class="hl-s">"60%"</span>]),
    PlaceholderRow([<span class="hl-s">"20%"</span>, <span class="hl-s">"40%"</span>, <span class="hl-s">"40%"</span>]),
    PlaceholderRow([<span class="hl-s">"90%"</span>]),
  ]);
}
</code></pre>

<p>I found this pretty simple and cool and plan on using it on future projects in similarly constrained environments.</p>

<h2 id="poor-mans-oauth2">Poor man’s OAuth2</h2>

<p>Then there was the matter of authentication and authorization.</p>

<p>The reader needs to be able to go to <code>your-jekyll-site.com</code> and either be shown the post’s content or a paywall with a “Subscribe” link. After they follow the link and complete the subscription process, they must be redirected back to the post and, this time, be shown its content. Next time they access the post – or any other post from that site – they must already be logged in and immediately shown the content.</p>

<p>Initially, I had thought of a very simple system. After the reader would log into <code>app.subscriber-only.com</code>, the session cookie would be set. This cookie would then be available on writer’s sites because the script using this cookie would be served from the same origin at <code>app.subscriber-only.com/so.js</code>.</p>

<p>Turns out this would have worked several years ago but no longer does. A cookie from <code>app.subscriber-only.com</code> on <code>your-jekyll-site.com</code> is considered a “third-party cookie”. These cookies are being phased out by browsers and are no longer sent with requests because they were being used by ad companies to track users across sites. This is why we can’t have nice things.</p>

<p>I ended up implementing a flow similar to OAuth2’s Authorization Code Grant<sup id="fnref:2"><a href="#fn:2" class="footnote" rel="footnote" role="doc-noteref">2</a></sup> but with less ceremony. It goes like this.</p>

<p>First, the reader clicks the “Subscribe” button on the paywall and gets redirected to <code>app.subscriber-only.com</code>. They can then create their account, input their credit card details and complete the subscription flow. At the end of the flow, they’ll have a “Go back to the post” link.</p>

<p>This link will have a <code>?code=&lt;randomly generated nonce&gt;</code> query parameter. The nonce is stored on the database and associated with the reader.</p>

<p>The <code>so.js</code> script reads the <code>code</code> from the query string and issues a request to <code>app.subscriber-only.com/api/v1/access_tokens</code> which includes the said code.</p>

<p>The code is verified to exist, deleted and an access token is returned in its stead. This access token is stored in a (first-party) cookie and passed in all further requests going out to <code>app.subscriber-only.com</code>.<sup id="fnref:3"><a href="#fn:3" class="footnote" rel="footnote" role="doc-noteref">3</a></sup></p>

<p>Unless the reader decides to clean their browser’s cookies, they’ll be authenticated from now on. The disadvantage, when compared to the naive approach I initially started with that didn’t work, is that the reader won’t be automatically authenticated if they go to <code>another-jekyll-site-using-so.com</code>.</p>

<h2 id="phoenixs-contexts-in-rails">Phoenix’s Contexts in Rails</h2>

<p>SO’s backend is written in Ruby on Rails.</p>

<p>The general Rails recommendation, when it comes to code organization, is to push all your business logic into the model and keep your controller as lean as possible. I agree with the latter part but not so much the first. You can end up with huge models, which complicates maintenance, and relying too much on Rails’ callbacks which make code flow harder to understand.</p>

<p>The usual solution to this, in the Rails world, is to use Service Objects. The usual implementation of the Service Object goes like this.</p>

<pre><code class="language-ruby"><span class="hl-k">class</span> ApplicationService
  <span class="hl-k">def</span> <span class="hl-k">self</span>.call(*args, &amp;block)
    new(*args, &amp;block).call
  <span class="hl-k">end</span>
<span class="hl-k">end</span>

<span class="hl-k">class</span> CreateUserService &lt; ApplicationService
  <span class="hl-k">def</span> call(email)
    user = User.create!(email:)
    
    UserMailer.with(user:).welcome_email.deliver_later
    
    user
  <span class="hl-k">end</span>
<span class="hl-k">end</span>

<span class="hl-c"># Usage</span>
CreateUserService.call(params[<span class="hl-s">:email</span>])
</code></pre>

<p>This fits well into Ruby, it being an object-oriented language, but I find it inelegant and cumbersome as you end up with a ton of methods called <code>call</code>, classes named like methods and boilerplate inheritance.</p>

<p>The Phoenix framework – a.k.a. Elixir on Rails – has the concept of a <a href="https://hexdocs.pm/phoenix/contexts.html">Context</a>. These are pretty much the equivalent of a Service Object in a more functional language like Elixir.</p>

<p>I think Phoenix’s approach is much simpler and, if you also add in the recommended error handling strategy, you end up with more elegant and less boilerplatey code. The good news it isn’t tied to Elixir’s constructs and that is translates very easily to Ruby.</p>

<pre><code class="language-ruby"><span class="hl-k">module</span> Users
  extend <span class="hl-k">self</span>
  
  <span class="hl-k">def</span> create_user(email)
    user = User.new(email:)
    <span class="hl-k">return</span> [<span class="hl-s">:invalid</span>, user] <span class="hl-k">if</span> user.invalid?
    
    UserMailer.with(user:).welcome_email.deliver_later
    
    [<span class="hl-s">:ok</span>, user]
  <span class="hl-k">end</span>
<span class="hl-k">end</span>

<span class="hl-c"># Usage</span>
<span class="hl-k">case</span> Users.create_user(params[<span class="hl-s">:email</span>])
<span class="hl-k">in</span> [<span class="hl-s">:ok</span>, user]
  ...
<span class="hl-k">in</span> [<span class="hl-s">:invalid</span>, user]
  ...
<span class="hl-k">end</span>
</code></pre>

<p>The code is easy to understand and all of it is needed there’s not boilerplate and no yaks to shave. Better, no?</p>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1">
      <p>Let me know if you did it and I’ll give you credit. Thanks! <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2">
      <p><a href="https://datatracker.ietf.org/doc/html/rfc6749#section-4.1">https://datatracker.ietf.org/doc/html/rfc6749#section-4.1</a> <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:3">
      <p>You might be wondering, like I did, why do you even need an access token and why not just pass the code in all requests. This is because the link with the code might end up being stored – in the browser’s history, for example – which makes it likelier to leak. The access token is guaranteed to only have been stored in the cookies. <a href="#fnref:3" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="subscriber-only" /><category term="engineering" /><summary type="html"><![CDATA[I closed down Subscriber Only, here’s a couple of interesting things I did and learned while working on it.]]></summary></entry><entry><title type="html">More Bang for Your Buck</title><link href="https://0x1.pt/2023/07/15/more-bang-for-your-buck/" rel="alternate" type="text/html" title="More Bang for Your Buck" /><published>2023-07-15T00:00:00+00:00</published><updated>2023-07-15T00:00:00+00:00</updated><id>https://0x1.pt/2023/07/15/more-bang-for-your-buck</id><content type="html" xml:base="https://0x1.pt/2023/07/15/more-bang-for-your-buck/"><![CDATA[<p>Defining an API is one of the hardest challenges a software engineer has to go through. You’ll invariably have to take several guesses in regards to how the API will be used and how it will evolve, making it as future-proof as you can, or risk having to redo it with a <code>v2</code> prefix and doubling your maintenance effort.</p>

<p>I’ve read a lot of posts on the art of API-defining but I haven’t ever read one which proposes a method, which doesn’t always work but perhaps should be implemented when it can, and which is <strong>skipping the challenge altogether and not defining an API.</strong></p>

<p>Here’s what I mean.</p>

<p>Let’s consider the most basic GET request on an MVC-style server-rendered application. There’s essentially three steps.</p>

<ol>
  <li>A request is made to <code>/resource/1</code>.</li>
  <li>The controller fetches the model with ID 1 from the database.</li>
  <li>The view takes the model and uses it to render whatever is needed.</li>
</ol>

<p>Now, here’s the same thing in a client-rendered application.</p>

<ol>
  <li>A request is made to <code>/resource/1</code>.</li>
  <li>A bundle is downloaded which includes code to both render the view and download the data needed to render it from a well-defined API endpoint.</li>
  <li>A request is made to <code>/api/resource/1</code>.</li>
  <li>The resource with ID 1 is serialized into a well-defined schema and returned to the client.</li>
  <li>The client uses the resource to render the view.</li>
</ol>

<p>Pushing aside discussions of performance and whatnot, it’s clear that we had to do more development work on the second flow. We had to sit down and define an endpoint and a schema for a resource that’s returned from that endpoint while on the first flow we didn’t have to do any of this at all.</p>

<p>Here’s another, perhaps more controversial, example.</p>

<p>Our authentication system is composed of a <code>User</code> model and an <code>AccessToken</code> model. At some point we’re required to support a new authentication flow based on passkeys and hence decide to introduce a new <code>PassKey</code> model.</p>

<p>Solution number one is just placing the <code>PassKey</code> model at the same level as the <code>AccessToken</code> one. Same thing for the logic itself.</p>

<p>Alternatively, we could modularize.</p>

<p>Should we move all models to the <code>auth</code> package? Maybe just move the models that are directly related to authentication to the new package and keep <code>User</code> in <code>app</code>. But then we can’t be having <code>app</code> call into <code>auth</code> and <code>auth</code> into <code>app</code> because that introduces a circular dependency which is bad design. So let’s make <code>auth</code> into a library and introduce a well-defined API.</p>

<p>We just put ourselves up for more work in the name of modularization, expandability and “better” software design and yet have reached the exact same end result.</p>

<p>Now, before you curse me to the fiery pits of software development hell let me be very clear: <strong>there’s good reasons for having to go through this work.</strong></p>

<p>If scale requires it, you’ll have completely separate teams handling frontend and the backend codebases. Or you’ll have a team dedicated to handling authentication code. At this point you’ll need to be spending time building APIs.</p>

<p>But this is not the case for a good chunk of software companies. So, until you really, really can’t why not just do the simple thing?</p>]]></content><author><name>Vitor Sousa Pereira</name></author><category term="engineering" /><summary type="html"><![CDATA[Skipping having to spend time defining an API until you really, really need it.]]></summary></entry></feed>